
Two things called MCP have landed at once. If you’ve been wiring AI features into your product lately, you’ve probably already stood one of them up, and the naming collision is enough to make you wonder which one to back.
Backend MCP and WebMCP solve different problems at different layers of the stack, so the question is which interface applies where. This article covers the split, the sequencing risk, who’s on board, and how to trial WebMCP. For background, see the agent-ready web and how WebMCP actually works.
WebMCP versus backend MCP: what’s the difference and which applies to the web?
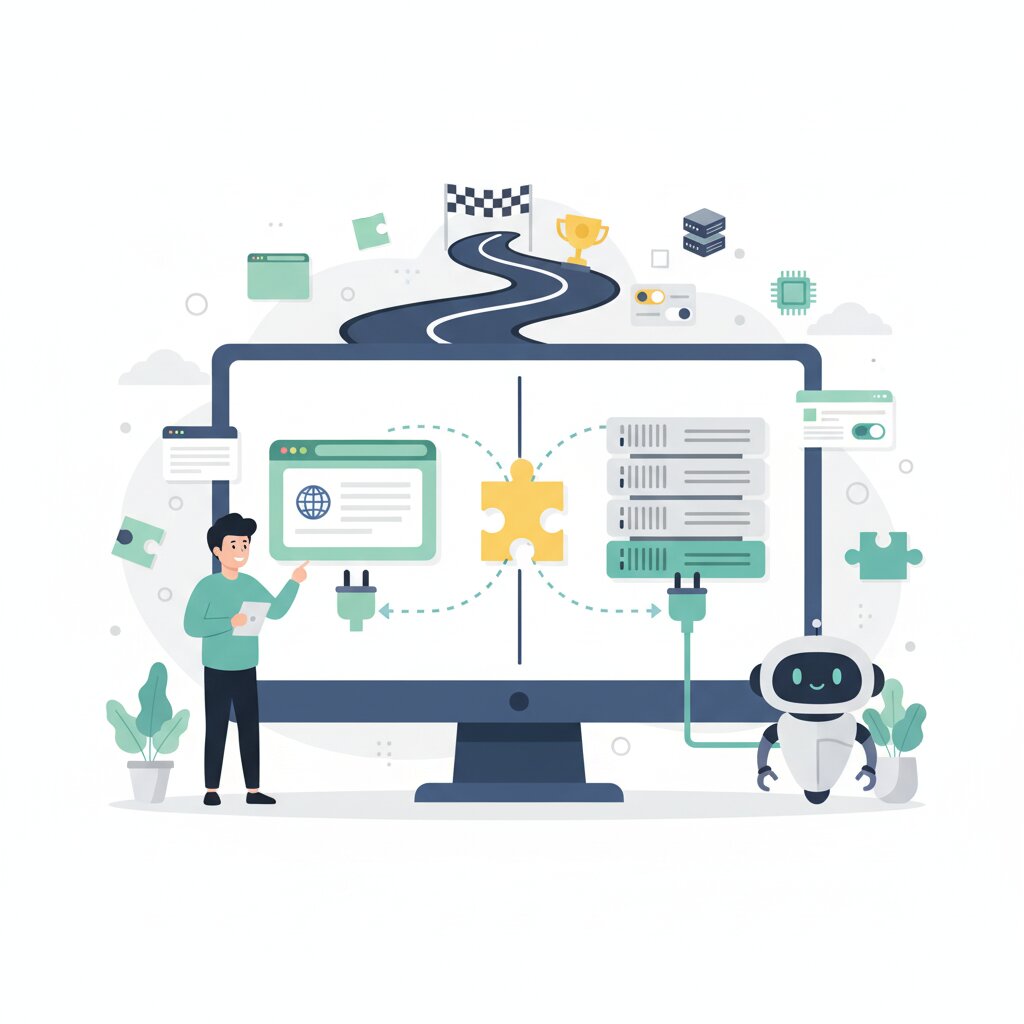
The difference is where the tool interface lives. Backend MCP exposes tools server-side, behind an API boundary, with no browser in the loop. WebMCP exposes tools on the page itself, for a browser agent working inside a live session. Neither replaces the other; most teams will run both.
Backend MCP is the settled layer. Anthropic announced it in November 2024 and later donated it to the Agentic AI Foundation under the Linux Foundation; MCP now numbers over ten thousand public servers. It connects agents to databases and APIs over Streamable HTTP, suited to hosted services and developer tooling.
WebMCP sits on the other side of the boundary. It’s a draft W3C Community Group spec from Google Chrome and Microsoft that lets a page declare tools to an agent, either by annotating HTML forms or registering tools in JavaScript through document.modelContext. It runs same-origin by default, suited to the public flows an agent completes in the page.
Because they share a contract, they compose cleanly in one stack. Both expose declared tools: a name, a description and a JSON Schema inputSchema. One comparison puts it neatly: WebMCP is SEO for AI agents, while MCP servers are APIs for AI applications. How WebMCP actually works covers the mechanics.
Sharing a contract does not mean the hard questions are settled. The interface is standardising first.
Why is the agent interface standardising before reliability and accountability are settled?
The tool contract is cheap to standardise and useful immediately, so it ships first. Long-task reliability is still unsolved, and accountability around audit, attribution and consent is immature. Standardising now is a bet on openness before safety is proven, so adoption has to stay reversible.
The interface is locking in while long-task trust stays open. Research on long-horizon reliability finds recent capability gains translate into only small reliability improvements, with open-ended tasks barely improving in the latest models. METR‘s time-horizon metric puts the current frontier at roughly 50 minutes of autonomous work at 50% reliability, which is a long way from the long-running jobs agents are being sold to run.
Accountability is thinner still. The WebMCP spec is explicit about the trust gap: no tool’s declared intent is guaranteed to match its behaviour, since agents rely on descriptions they cannot verify first. The hints meant to close that gap (readOnlyHint, consequentialHint, untrustedContentHint) are advisory, not enforced. Prompt injection tops the OWASP list, and tool poisoning hides malicious instructions in that same metadata.
Read the security case for slowing down and the long-task reliability problem before you assume the interface alone earns trust.
Chrome versus Firefox versus Safari: who’s actually on board?
Who resolves the open risk is a small, divided set of vendors. Chrome is the implementer, running the Chrome 149 origin trial, with Microsoft alongside via Edge. WebKit formally opposes WebMCP on API design, privacy, security and venue grounds. Mozilla is neutral, with no implementation. That coalition decides whether WebMCP becomes a web standard or a Chrome feature.
Chrome owns the momentum. An early preview landed in February 2026 and the Chrome 149 origin trial opened in June, and Microsoft runs a parallel Edge 150 trial, with Gemini in Chrome set to call the tools directly.
WebKit is the clearest counter-position. Its standards position is a formal oppose, listing API design, duplication, privacy, security and venue concerns, and arguing the work belongs in HTML and accessibility semantics rather than the Machine Learning Community Group. Safari controls the iOS browser-engine layer, so that opposition is a significant mobile gap.
Mozilla sits neutral, with no implementation listed and prompt-injection concerns noted only in passing. Mozilla’s neutrality is the swing vote.
The momentum signals are real but lopsided. OpenAI added Site tools to ChatGPT’s desktop browser in August, treating page-declared tools as untrusted, and Angular v22 ships experimental WebMCP support. Beyond Chrome and Edge, only Brave Leo is listed, and nothing for Firefox or Safari. The standardisation race is still undecided.
Is WebMCP worth adopting yet, given it’s still an origin trial?
An origin trial lets you ship WebMCP to opted-in Chrome 149 users while everything else falls back silently, but it does not commit you to a stable API. Adopt only as a reversible experiment: confirm your key flows can be declared as tools, your team has governance to expose them, and you can absorb interface churn.
It runs from Chrome 149 through 156, needs a valid origin-trial token, and is gated by a tools permissions policy keeping tools same-origin by default, per Chrome’s own guidance. That’s low risk, but the spec is still plastic: the imperative method’s name has already changed since early adopters shipped, and authentication is unresolved.
The better question is your own site’s readiness. Test whether your highest-value flows type naturally as declared tools: a checkout step does, an open-ended browsing journey usually doesn’t. If they don’t, WebMCP is premature for your business. Start with the passive signals, robots.txt content signals, an llms.txt map and a draft MCP Server Card, which make you discoverable without exposing anything callable.
Keep it reversible. Feature-flag the tools, keep your existing flows as the fallback, and plan for method-name and schema churn. Require human confirmation and log provenance for consequential actions, since consent and the build-versus-buy decision is where this gets real, and what sites get in return for serving agent traffic is still open.
The “WebMCP vs MCP” framing dissolves. Backend MCP is the settled server layer, WebMCP the contested in-page surface, and a sound architecture runs both.
You can’t decide whether WebMCP becomes a standard or a Chrome feature; Chrome, WebKit and Mozilla will decide that. What you can decide is how tightly you couple to it today, so let your own readiness be the gate. What all of this means for the web is still being written, so stay light on your feet.
Frequently Asked Questions
Is WebMCP going to replace backend MCP, or do I have to choose one?
No. WebMCP and backend MCP occupy different layers, so they are complements rather than rivals. Backend MCP exposes tools behind a server-side API boundary with no browser in the loop, while WebMCP exposes tools on the page for a browser agent working inside a live session. Most teams will run both: backend MCP for hosted services and developer tooling, and WebMCP for public web flows such as booking, checkout, and support.
Does WebMCP use the same tool schema as backend MCP?
Yes, in substance. Both interfaces expose declared tools described by a name, a natural-language description, and a JSON Schema inputSchema, which is why they compose cleanly in one stack. The contract is deliberately shared so an agent can reason about a tool the same way wherever it sits. The real difference is transport and trust domain, not the shape of the tool definition itself.
What’s the difference between WebMCP’s Declarative API and Imperative API?
The Declarative API annotates existing HTML forms with attributes such as toolname, tooldescription, and toolautosubmit, so the browser can generate a tool schema from markup you already have. The Imperative API registers tools dynamically through modelContext.registerTool(), giving you finer control over behaviour. Both expose declared tools, but the declarative half sits materially closer to vendor consensus, which is part of why the spec is still being argued over.
What happens to my WebMCP tools in browsers that don’t support them?
They degrade silently. WebMCP is designed for progressive enhancement, so in browsers without support your annotated forms and registered tools simply behave as ordinary web features, with no error shown to the user. That is what makes an origin trial relatively low risk: you ship the tools behind a flag to opted-in Chrome 149 users while everyone else continues on the existing experience.
Does adopting WebMCP lock me into Chrome?
Not if you adopt it reversibly. WebMCP is currently a Chrome-led origin trial, so you are shipping to opted-in Chrome 149 users rather than committing to a stable, multi-vendor API. Feature-flag the tools, keep your existing flows as the fallback, and plan for method-name and schema churn. The lock-in risk comes from coupling tightly to a churning draft, not from trialling it.
Is WebMCP a genuine web standard or just a Chrome feature?
It is a draft standard, not yet either. WebMCP sits in the W3C Web Machine Learning Community Group as a draft and is not on the W3C Standards Track, while Chrome runs the Chrome 149 origin trial. Whether it becomes a neutral web standard or a single-vendor capability depends on Mozilla and the Safari side, and that outcome is still undecided.
How do I make my site agent-ready without adopting WebMCP yet?
Start with the passive signals before the active ones. A robots.txt with content signals, an llms.txt content map, and a draft MCP Server Card at /.well-known/mcp/server-card.json make your site discoverable without exposing any callable capability. Audits such as Cloudflare’s isitagentready.com and the Lighthouse agentic browsing check score these basics, which are cheaper and lower risk than declaring WebMCP tools.
How do I know if my site’s key flows can be expressed as declared tools?
Test whether each flow has a clear action, typed inputs, and a defined outcome. A booking or checkout step with parameters and a success state types naturally as a declared tool, whereas an open-ended browsing or comparison journey usually does not. If your highest-value flows cannot be described that way, WebMCP is premature for you regardless of the standard’s status.
Should I expose every flow on my site as a declared tool?
No. Expose the flows where an agent acting on a user’s behalf adds clear value and where you have governance to control the action. Start with a small number of high-intent tasks such as checkout, booking, or support requests, and require human confirmation for anything consequential or irreversible. Declaring tools you cannot audit or constrain increases risk without improving the experience.
What is a WebMCP annotation hint, and can a browser agent trust it?
Annotation hints are boolean metadata such as readOnlyHint, consequentialHint, and untrustedContentHint that signal a tool’s behaviour to the calling agent. Treat them as advisory, not enforced: the spec does not guarantee a tool behaves as its hint claims. Because descriptions and hints are themselves a manipulation surface, hints should trigger scrutiny, especially human confirmation for anything marked consequential.
Can browser agents use my site without WebMCP at all?
Yes, but through a more brittle path. Without declared tools, agents fall back to DOM scraping and screenshot-and-click automation, which guesses at intent from pixels, coordinates, and markup. That approach breaks on layout changes and costs more tokens. WebMCP exists to replace that guesswork with a typed contract, so sites that declare tools tend to be more reliably operable.