

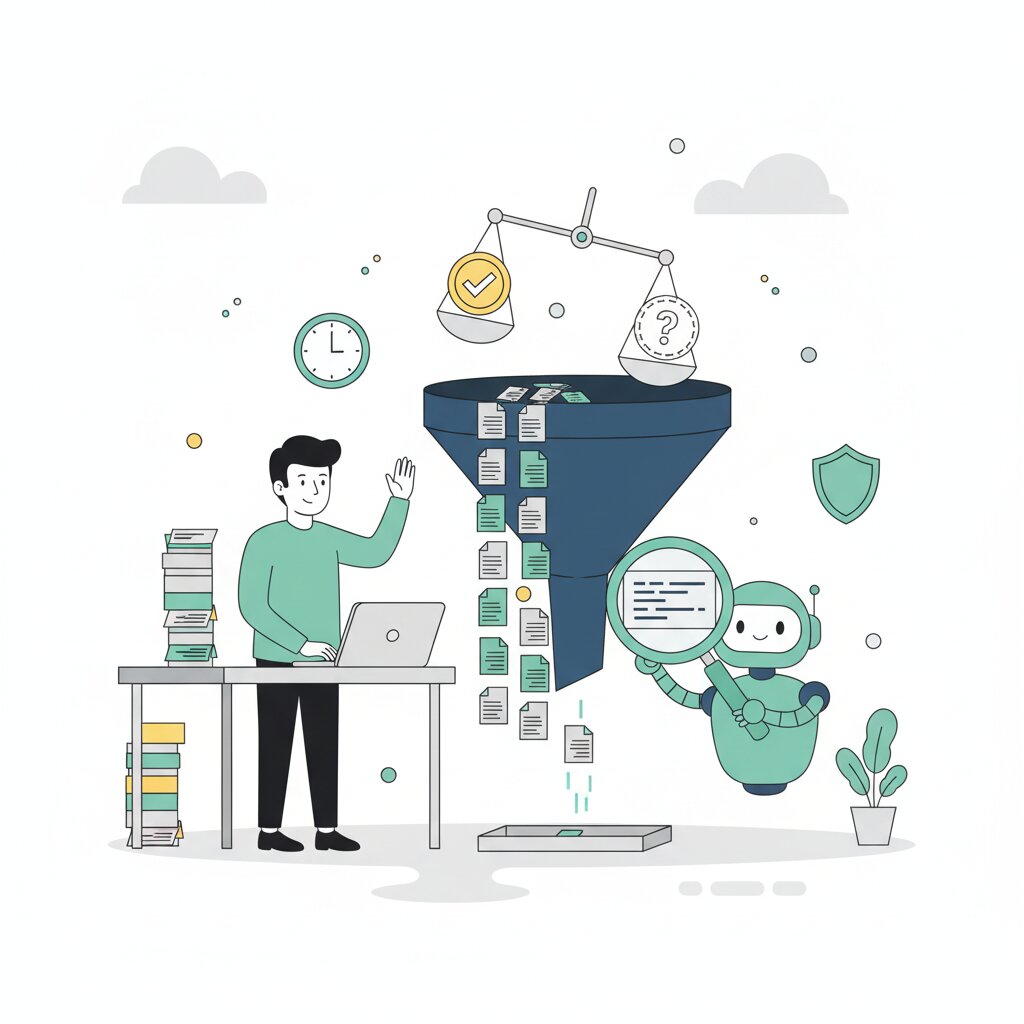
GitHub commits nearly doubled year over year, crossing 1.4 billion a month, while the senior hours available to your team stayed flat. AI made writing code cheap and fast and left checking at human pace. Commit volume and review hours stopped moving together, and code review is where they cross.
Modern code review rests on one assumption: a human reads what ships. The practice descends from Michael Fagan’s 1976 inspection method, a bounded, human-paced queue. Agentic coding removed that bound. When an agent opens a pull request in minutes, the queue becomes the constraint.
The adoption numbers show the gap: code generation sits at 40.2% and review at 37.7%, while CI/CD, the checking side, is at 13.2%. Writing is adopting far faster than verification, and that lag is where risk concentrates. Pull requests wait longer and unreviewed merges are routine. The bottleneck moved from producing code to verifying it, and this page maps the problem rather than prescribing a fix.
In This Series
- Why Code Review Became the Bottleneck and What the Numbers Show: the board-level evidence.
- What Happens to Reviewers When Review Volume Outruns Capacity: surrender and exploitation.
- How AI Code Review Tools Compare on Real Bug Detection and Noise: what machines catch.
- How Stacked Pull Requests and Context Engineering Reduce Review Load: the process fixes.
- What Teams Lose When No Human Reads the Code Before It Ships: the senior engineer tax.
- How to Govern Code Review When Machines Start Approving Changes: routing, audit evidence and spend.
Why did AI break code review rather than make it faster?
Writing code used to be slower than reading it, so review was never the constraint. Agentic coding inverted that ordering: commit volume climbed while the senior hours available to read changes stayed flat, so the queue became the constraint and the bottleneck moved from producing code to verifying it. AI-generated pull requests wait about 4.6 times longer for review than human-written ones, and Faros telemetry shows pull requests growing by half in size. Time-to-first-review, review duration and review-to-merge now need separate tracking, and the full numbers sit in why the constraint moved to verification.
Reviewers do not scale with volume. Surrender, approving without reading while policy still requires review, and exploitation, absorbing an unworkable queue, are predictable responses to pressure rather than discipline failures. They mark a saturated gate, and the fix is structural. That human side is what happens to reviewers under volume.
What can you actually trust machine review to do?
Machine review is strong at pattern-level defects at volume — null handling, resource leaks, injection surfaces, inconsistent error paths — and weak at intent, because judging intent means knowing what a change was meant to do. The honest ceiling sits at 60.8% F1 on Martian’s independent Code Review Bench, and scale of deployment proves nothing about accuracy. Two facts bound what you can trust it with: it shares blind spots with the code it reviews, and a second model from the same family is not a second opinion.
The obvious next step is to point a machine at the queue. Microsoft’s PRAssistant covers over 90% of its pull requests, and widespread use does not equal reliable detection. F1 also balances detections against false alarms, hiding the trade-off you care about: false positives in reviewer attention. What matters is detection rate versus noise.
The structural risk is correlated blind spots. When the same model family writes and reviews the code, shared failure modes are expected rather than bad luck. Context hallucination and prompt injection rarely appear in comparison tables, yet decide whether machine review helps or hurts. The tool-by-tool evidence sits in how AI review tools actually score.
How do process changes restore reviewability?
Reviewability is mostly an input problem, not a reviewer problem. Two structural changes do the heavy lifting: shrinking the unit of review through stacked pull requests, and improving what the author hands over through intent and context engineering. Smaller dependent changes lower per-review load and make author-side verification visible before a reviewer is asked to look, which matters more than raw reviewer speed.
Stacked pull requests break one large change into small, dependent units, which solves a comprehension problem. Feature flags solve a release problem instead, hiding unreviewed code in production rather than making it reviewable, and confusing the two is common. The peer evidence skews to very large organisations, so for a 50 to 500 engineer team stacking is a hypothesis to instrument rather than a proven transplant.
Intent-driven verification declares what a change is meant to do before review; context engineering decides what the model, and therefore the reviewer, is given. Both move error discovery upstream, where it is cheap. Context work compounds across every model you adopt, while tooling work is replaced the moment you switch vendors. The mechanism is the subject of stacking changes and engineering context.
What still needs a human, and how do you prove it?
Two decisions cannot be delegated: which changes carry enough consequence to warrant a named human, and whether your approval evidence survives scrutiny. Route by blast radius rather than line count, because a four-line change to an interest calculation outranks a 400-line change to an internal admin page. In a regulated environment, “the model approved it” is not an accountability answer; a named human stays accountable for the control itself, and the proof is an evidence trail that survives audit.
The senior engineer tax concentrates review and repair on your most experienced people, because agent output fails in ways only experience detects. Cognitive debt, the gap between what the system does and what the team understands, accumulates when no human reads the code, and review used to carry mentoring as a by-product. Neither cost shows up in a throughput metric. That human ledger is the cognitive debt nobody reports.
What remains is governance: risk-based PR routing and agent sign-off define the boundary of delegated authority, and because PR count and cycle time both improve when review gets worse, proof has to be evidence rather than throughput. Build-versus-buy under metered pricing is a governance decision in disguise, and the full argument lives in routing, audit evidence and spend.
Resource Hub: How AI Broke Code Review — Deep Dives
Read them in sequence: diagnose, measure, delegate.
Diagnosis: what broke
- Why Code Review Became the Bottleneck and What the Numbers Show: the evidence for the board.
- What Happens to Reviewers When Review Volume Outruns Capacity: why the agents-write-humans-review model becomes rubber stamps.
The replacement: capability and process
- How AI Code Review Tools Compare on Real Bug Detection and Noise: benchmarks, noise, and the ceiling.
- How Stacked Pull Requests and Context Engineering Reduce Review Load: the fixes that shrink what reaches review.
The human and governance line
- What Teams Lose When No Human Reads the Code Before It Ships: cognitive debt and the senior engineer tax.
- How to Govern Code Review When Machines Start Approving Changes: routing by blast radius, audit evidence, and build-versus-buy.
The decision underneath is not whether to adopt machine review, but what still requires a human and how you prove it.
Frequently Asked Questions
Is code review actually broken, or is it just busier than it used to be?
It is broken in a specific sense: the founding assumption no longer holds. Review was built for a bounded queue where a human reads what ships, and that bound disappeared when agents began opening working pull requests in minutes. Volume alone might look like a staffing problem; the loss of the assumption is not. Busy is a symptom, not the diagnosis.
How do I tell whether my review queue is a capacity problem or a process problem?
Look at where the delay accumulates. If pull requests sit untouched for days, the constraint is reviewer hours. If they move quickly but arrive large, tangled and without stated intent, it is a process problem, and more reviewers will only absorb it. Compare waiting time against change size and unreviewed merge rate before you ask for headcount.
Does hiring more reviewers fix an AI-driven backlog?
Not on its own. Reviewers do not scale with volume, and the senior hours you need are the scarcest kind to hire. Adding people to an unshaped queue buys time and hides the structural problem, because the queue refills at machine speed. Hire where the evidence points, but shrink what reaches review first. Smaller changes and declared intent raise capacity without a single new head.
Why does a 60.8% F1 score matter if the tool still catches real bugs?
Because F1 folds precision and recall into one number, and both decide whether a tool earns its place. A tool that catches real defects but buries them in noise trains reviewers to skim, which is surrender by another route. A tool that misses half the defects creates false confidence. The score is a ceiling on independent detection, not a verdict on your deployment.
Is it true that a different AI model gives you a genuine second opinion?
Only if it is a genuinely different model family. When the same family writes and reviews, both inherit the same training gaps, which is what correlated blind spots means: a defect one cannot see is a defect the other cannot see either. Cross-family review narrows the overlap, but it is not an intent check, so a human remains the only real second opinion on what a change was meant to do.
Is it true that AI review tools make senior engineers unnecessary?
No. Machine review is strong at pattern-level defects and weak at intent, and intent is exactly what senior engineers judge. The senior engineer tax concentrates review and repair on your most experienced people precisely because agent output fails in ways only experience detects. Tools reduce the volume of trivial checks; they do not absorb the judgement calls that remain.
What happens if we let AI approve low-risk pull requests without a human?
You get throughput and you take on accountability risk. Risk-based routing can delegate low blast radius changes, but only if you have defined what low risk means, logged the evidence, and kept a named human answerable for the policy. In a regulated environment, “the model approved it” is not an accountability answer. Set the boundary before the first automated approval, not after.
How small does a pull request need to be before stacked review helps?
There is no universal line count, and treating one as a rule misunderstands the mechanism. Stacking works by breaking a change into dependent units that can be read in sequence, so the test is whether each unit carries one idea a reviewer can hold in mind. Most of the evidence comes from large organisations, so treat any threshold as a hypothesis to instrument on your own queue.
What is cognitive debt, and can you actually measure it?
Cognitive debt is the gap between what the system does and what the team understands. It accumulates when code ships without a human reading it, and it is hard to measure directly. Proxies are the honest route: how long a senior engineer needs to explain an unfamiliar module, how often incidents trace to code nobody remembers writing, and how much review still functions as mentoring.
Can a pull request trick an AI reviewer into approving something dangerous?
Yes, and it is an underreported risk. Prompt injection embedded in code comments, commit messages or issue text can steer a reviewing model, and context hallucination can make it assert properties the code does not have. Neither shows up in benchmark tables, which is why they matter. Treat review output as untrusted input and keep a human on changes to authentication, payments and data access.
What should we measure instead of PR count and cycle time?
Measure what escapes, not what moves. Track defect escape rate, the proportion of merges with no human reader, the time a change waits before first review, and rework attributable to changes that passed review. PR count and cycle time both improve when review gets worse, which is why they cannot be your evidence. Pair each metric with the risk tier it belongs to.
Who is accountable when an AI-approved change causes an incident?
A named human, by design. Delegation changes who does the checking, not who owns the outcome, so your policy needs to name the person accountable for each risk tier before automated approval is switched on. Audit evidence should show the routing decision, the checks performed and the human who accepted the residual risk. Otherwise the question has no answer under scrutiny.